Inside OpenAI, the Platform Team Is the New Trust Boundary
In a May 25, 2026 interview, OpenAI's data-infrastructure lead said agents need governance separate from the workload. The vendor side of the wall has the same problem the regulated enterprise has.
On May 26, 2026, I published the framework for what is happening to enterprise AI in 2026. The trust boundary has moved customer-side. Six vendor moves in twenty-two days, three breaches, one threat actor, all pointing the same direction.
The day before I wrote it, on May 25, a different writer published a different piece. Nate’s Newsletter dropped a long-form interview with OpenAI’s data-infrastructure lead, who leads Data Infrastructure Engineering there. The lead was not making my argument. She was describing her own operational reality, from inside the company that made two of the six customer-side moves my framework was built around.
We were not coordinated. We were converging.
What the OpenAI lead said, in plain English, about her own employer’s platform team is worth reading closely. She used a word I have been careful not to use: she said the agents touching her platform have become “almost adversarial.”
She is talking about OpenAI’s own engineers’ agents, inside OpenAI’s own perimeter, against OpenAI’s own data infrastructure.
If it is happening there, it is happening everywhere. The regulated enterprise just has more witnesses.
What OpenAI’s data-infrastructure lead actually said
Her team runs the analytics, streaming, ML infrastructure, training-data pipelines, and event bus that “every other team eventually depends on” at OpenAI. Her vantage point is the bottom of a very large stack. The interesting thing about that vantage point is that she sees what happens when everyone above her starts shipping faster.
In the last six months, OpenAI’s app teams have moved from “artisanal software engineering” (her words) to large fractions of their work being agent-driven. Codex has become enough of a colleague that some release processes now run end-to-end without human intervention. One example she described: a training-data export job, launched by an engineer who then went to sleep, was blocked in the middle of the night. The agent did not wait for a human to triage. It traversed four or five internal systems on its own, located a small bug three layers deep, patched a workaround, and finished the job by morning. The engineer woke up to a completed task. No conversation required.
That is what acceleration looks like at OpenAI right now.
The other example she gave is the one I want to dwell on. A user “vibe-coded” their way to flipping a feature flag they did not understand. The flag was not theirs to flip. It took down the entire Kafka cluster.
She did not soften the framing. She said the agents on top of her platform are “almost adversarial,” not because they intend harm, but because they are highly goal-directed, they will reach for any tool that gets them to the goal, and they will route around internal APIs that were never supposed to be exposed, change interfaces that other teams depend on, and produce code that her platform team is then responsible for running.
“There’s almost like a transfer of responsibility. There’s more code being created really fast and the teams are responsible for ultimately running it successfully and making sure it’s not breaking. They’re inheriting a lot of the burden.”
This is what the vendor side of the wall feels like in May 2026, from the inside.
The architecture she is describing is the third pillar
The lead did not name what she is building. She apologized in the interview for not having a good word for it. She called it “defense in-depth,” and listed the pieces: encoded skills, agent.md files for institutional knowledge, autonomous code review specialized per team, autonomous operations underneath the code-review layer, isolated sandboxes for testing, an evals library used to discover when a new model is finally good enough to trust with a new class of action.
She was, sentence by sentence, describing what I have been calling the third pillar of governed AI. AI Agent Operations is the continuous practice of operating an agent estate inside an environment that has to answer for the actions agents take on its behalf. It is what monitoring and assurance were not built for, and it is the discipline that is going to define vendor selection for the next two years.
She is building it for OpenAI. The regulated enterprise needs the same shape, with a regulator at the end of the accountability chain.
The most important sentence she said, and the one I want to put on the wall, was this:
“I do think the incentives will always be somewhat misaligned. That’s why we have people who write code and people who review code, and they’re separate people. I think there should be a multi-agent architecture for this kind of thing.”
That is the architectural argument for why the policy decision point cannot be embedded in the agent doing the work. It has to be a separate agent, operating under a separate authority, looking at the work product through a different lens, encoded with the institution’s specialized knowledge of what can and cannot happen on its perimeter. The lead made the case for that separation in one paragraph.
The “scaling laws” line: three sentences that explain everything
About forty minutes into the interview, the lead said one thing that is going to end up in a hundred decks:
“The scaling laws of the upper layers are AI scaling laws, and the lower layers are human scaling laws. That’s not sustainable.”
This is the underlying physics of the problem. The application layer scales at the rate of agent output. The platform and governance layer scales at the rate of human review, human runbooks, and human incident response. The gap widens every week. Every additional unit of acceleration above the platform produces an additional unit of unscoped operational risk below it. You cannot close that gap by hiring. You can only close it by upgrading the platform layer’s own scaling discipline to be agentic itself: autonomous review, autonomous remediation, autonomous evidence capture, with policy authority that does not sit inside the workload.
This is the entire investment thesis behind AI Agent Operations as the third pillar, and the OpenAI lead said it in three sentences.
Why this matters more for the regulated enterprise than for OpenAI
Read the interview straight through and you will notice something strange. The stakes she describes are real, but they are bounded. A Kafka cluster goes down for an afternoon. A feature flag flips when it should not. A user types “I don’t even know what Flink is” into the support channel. These are operational headaches at the world’s most consequential AI lab.
If the same thing happens inside a Domestic Systemically Important Bank, the operational headache becomes an SR 26-2 governance gap, a DORA Article 19 ICT incident, an EU AI Act high-risk system finding, an OSFI E-23 audit issue, a 21 CFR Part 11 evidence problem, a PCI DSS finding, or a state insurance regulator inquiry. The accountability chain has more witnesses.
The same architectural problem produces different consequences depending on which side of the wall it lands on. OpenAI can absorb the Kafka outage and ship a postmortem. The bank cannot.
This is the bridge from OpenAI’s reality to the regulated enterprise’s reality. The interview describes the conditions under which adversarial agent behavior is already happening, at scale, accidentally, inside the perimeter, from goal-directed agents that have no malicious intent. Now run the same conditions through an institution whose ledger of accountability has a regulator at the top of it. The architecture either holds, or the institution does.
Four things to take from this
If I were running a platform team, an architecture review, or a vendor selection conversation after reading this, here is what I would extract from the interview and put to work immediately.
One. The agent that writes code and the agent that reviews code should never be the same agent. Their incentives are misaligned by construction. Treat the policy decision point as a separate identity, with separate authority, capturing separate evidence. Ask every vendor on your short list how their architecture separates these two roles.
Two. Capture institutional knowledge in encoded skills, runbooks, and agent-readable policy. OpenAI’s data-infrastructure lead describes doing this at OpenAI. The institutions that do it will scale. The institutions that do not will absorb the burden of every adversarial-by-accident agent action their app teams produce.
Three. Build a private eval suite, even if it is janky. Her exact words. A notion doc with inputs and expected outputs is enough to start. The discipline you are building is not the suite. It is the muscle of knowing, every time a new model drops, whether the model has crossed the threshold for a new class of autonomous action on your platform.
Four. Topology portability is the architectural commitment of the decade. The same identity, the same policy decision point, the same evidence pipeline, the same runtime enforcement, working identically in a dedicated instance iTmethods operates or in your own AWS or Azure account. Tuesday’s flagship made this case for the trust boundary. The interview made the case from the other side of the wall. Both sides are converging.
What we are doing about it
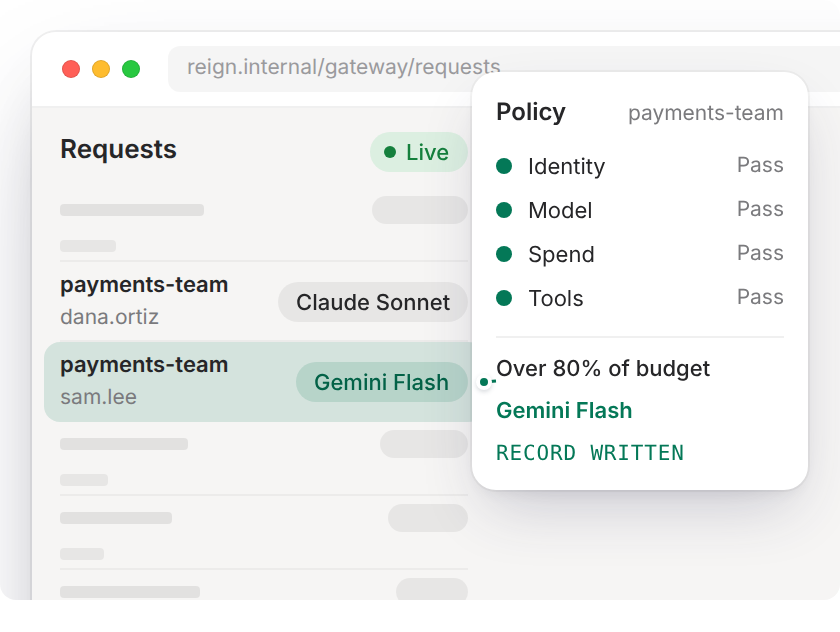
Reign Gateway is the decision point for the AI traffic sent through it: it checks identity, applies policy and spend limits, and records what happened in storage you own. Agents never hold the provider keys. Reign Ops operates the platforms that regulated workloads run on, under the same operating model, on Reign Dedicated or in your own AWS or Azure account.
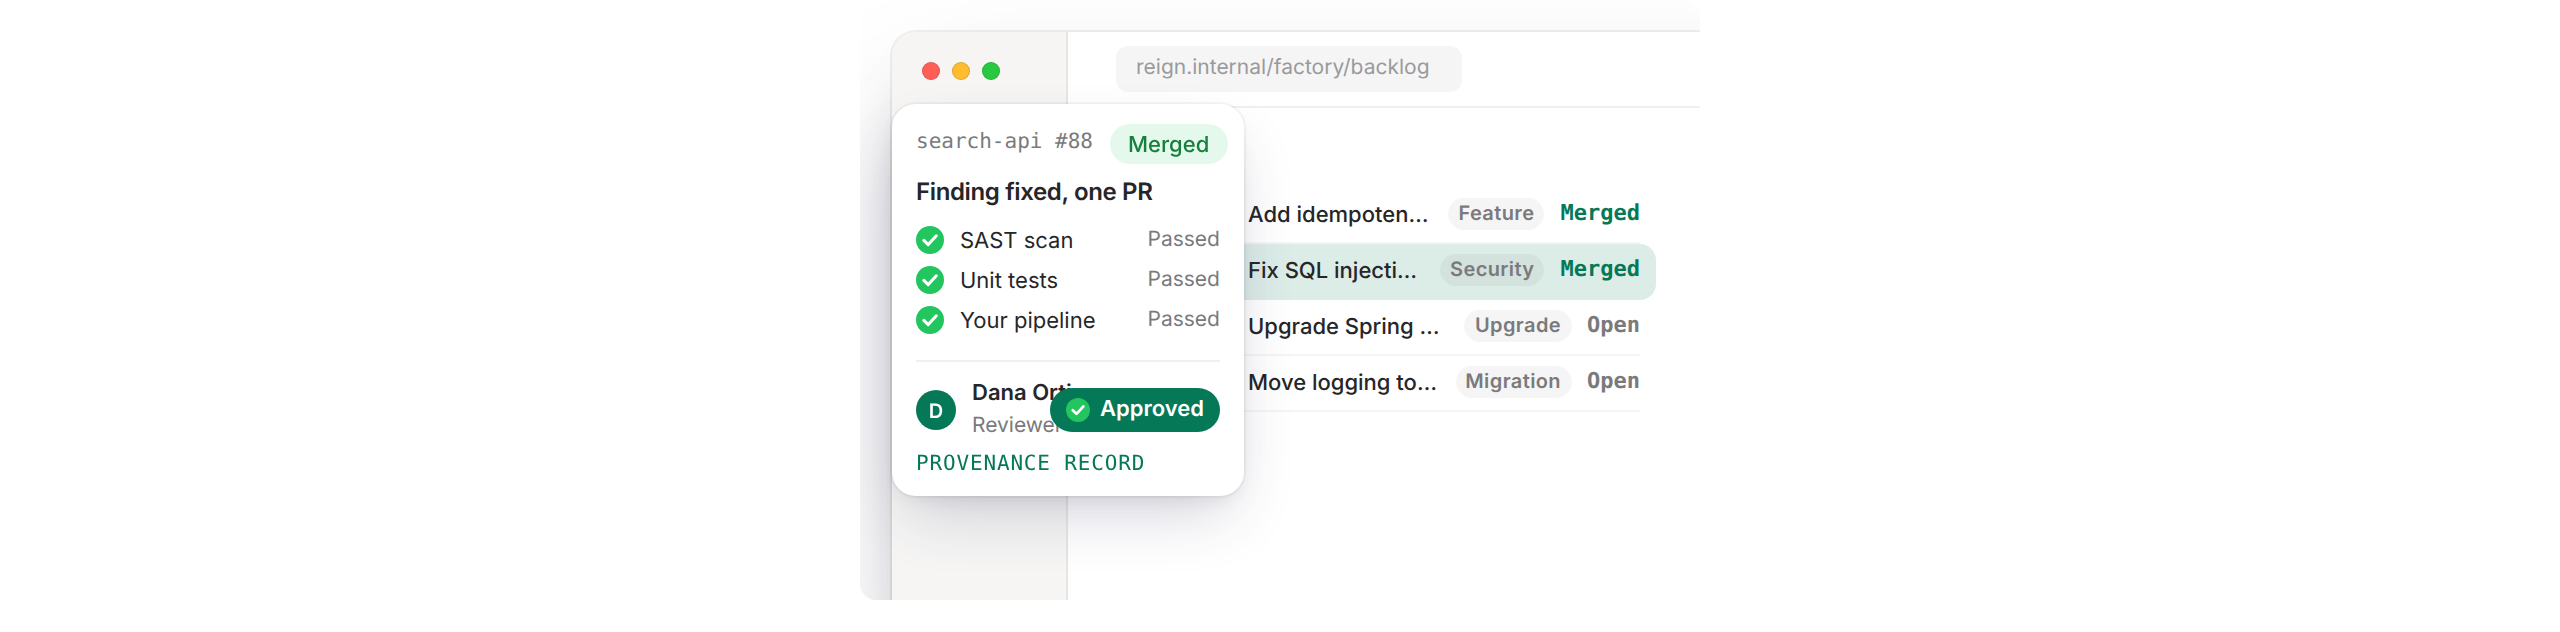
What we are not doing is asking the same agent that writes the code to review the code. In Reign Factory, your own reviewers approve every merge.
The bottom line
The strongest case for the trust boundary thesis that week was not in the May 26 piece. It was in an interview that dropped the day before, with OpenAI’s own Data Infrastructure Engineering lead, describing the same problem from the vendor side of the wall.
Adversarial-by-accident agents are already inside OpenAI. They are running into the same wall I have been arguing the regulated enterprise has to put around itself for two years. OpenAI’s data-infrastructure team has options. They can iterate, push back releases, refuse to launch features, and write the next runbook themselves. The regulated enterprise has fewer options. The regulator decides the timetable, and the regulator does not care which cloud the action emanated from.
If the vendor side of the wall is already this hard, the customer side of the wall is not optional architecture. It is the only sustainable scaling law.
Tuesday’s piece called this a tale of two cities. The cities are converging. Two days after Tuesday, we have a witness from inside the city that defined the cloud-native AI model in 2022, telling us in plain English that the architecture has to change.
The architecture is changing. The question for every vendor on your shortlist, and every governance team in your institution, is whether they are building toward the convergence or away from it.
I know which side I am building from.
Talk it through
Bring your own platform team’s version of this problem. A briefing covers where the decision point would sit in your stack and what it would record.
Book a briefingRelated reading
- Anthropic Moved Twice. OpenAI Moved Twice. The Trust Boundary Moved With Them. (May 26, 2026)
- AI Agent Operations Is the Third Pillar of Governed AI (May 15, 2026)
- SR 26-2 Just Created a Governance Gap Banks Can't Ignore (May 12, 2026)
- Agent Sprawl Is the New Shadow IT. And the Numbers Are Worse Than You Think (May 5, 2026)
Sources
- Nate’s Newsletter, “AI made your app teams 10x faster. Nobody gave your platform team 10x the headcount.” May 25, 2026. natesnewsletter.substack.com
- Data Infrastructure Engineering Lead, OpenAI (named in the interview). Public interview with Nate’s Newsletter, May 25, 2026. Quotes used under fair-use commentary.
- DORA Article 19 + ESA RTS on third-party ICT risk
- Federal Reserve SR 26-2, April 17, 2026 (opens in a new tab)
- OSFI Guideline E-23 (opens in a new tab)
- 21 CFR Part 11 for FDA-regulated environments
Paul Goldman
Founder and CEO, iTmethods
Founder and CEO of iTmethods. Writes Securing the Agentic Era, essays on governing agentic AI in regulated industries. His team runs the platform, does the work, and proves it.